One system.
From the machine to the fleet.
One system for AI compute beyond the cloud.
Cloud to air-gapped to denied link.
[ Platform ]
One install. Every environment.
The operating layer between every AI workload and the metal. Any network. Any site.
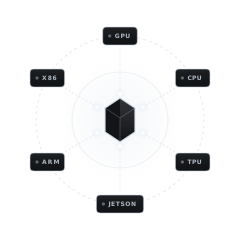
Built to run across hardware
GPU, CPU, TPU or mixed. Sector88 probes the box and configures itself for what is there. A CPU-only field server, a single Jetson at a ground station, or a rack of H100s in a SCIF. Same install, same API.
Deploys to any environment
Cloud, on-prem, edge, air-gapped, or fully disconnected. Install over a clean network or an empty one. Same system. Same API.
Stays on your side of the wire
Compute runs inside your network. Built for zero egress. No metered tokens. Prompts, responses, weights, and traces stay inside your perimeter.
Fig 1.1
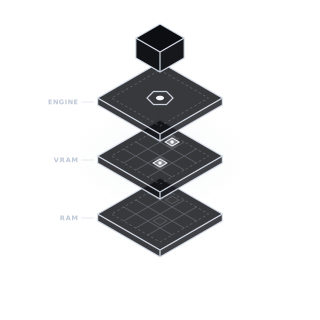
On the machine
Runs AI compute on every machine. Probes the hardware, places the workload, tiers memory, exposes one API. Field server to rack.
Explore RuntimeFig 1.2
Across the fleet
One control plane for every node. Deploy, monitor, pin, and roll back across your entire fleet.
Explore HubFig 1.3
Forward-Deployed Engineers
Audit, install, benchmark, harden. Our engineers embed in your team until you are live in production.
Explore FDEOne layer across the metal.
Every major GPU, CPU and edge accelerator. One install.
Hardware Platforms
Inference Backends
Technology
How it works under the hood
Compute placement, memory orchestration and the layers that hold it together.
Inside the platformBenchmarks
Cited engine numbers, hardware envelope
Engine throughput across vLLM, TensorRT-LLM and llama.cpp. Field proof under sustained load.
See benchmarksHardware
Compatibility matrix
NVIDIA, AMD, Intel, Apple Silicon, ARM, CPU-only. What runs on what, with sizing per workload class.
Open the matrixRun it where the cloud can’t reach.
Bring in our forward-deployed engineers, or install it yourself.